


The following guide is based on a presentation given by Maksymilian Jaworski, Data Engineer at STX Next, during our PowerIT Conference to celebrate 30 years of Python. Head over here to watch the full recording of Maksymilian’s webinar on the subject: https://www.youtube.com/watch?v=JbRIWW1j3Nw.
What is data engineering?
When executive reports show conflicting numbers or a critical data dashboard goes down during business hours, the issue is rarely the analytics software, but rather a break in the underlying data pipeline.
Businesses generate massive volumes of raw data daily, including sales performance, customer feedback, inventory metrics, and operational logs. However, this raw data is usually fragmented, inconsistent, and unstructured. Converting these raw inputs into clear, usable information presents significant data engineering challenges: handling sudden schema changes, managing storage costs, and avoiding data delivery delays.
Data engineering is the discipline focused on solving these operational problems. It involves building and maintaining the automated infrastructure that collects, transforms, and stores data, ensuring that business intelligence, data science, and product teams can rely on clean, accurate information when they need it.
Who are data engineers?
Data engineering is a skill that’s been steadily rising in demand over the years. Data engineers work on making raw data usable for further data-driven work by data scientists, data analysts, and all other end users within an organization.
They work with databases, cloud data platforms, processing frameworks, APIs, and orchestration tools to keep data moving reliably and in a usable form.
The primary responsibilities in this role include:
- Maintaining data pipelines: Building and monitoring automated workflows to prevent data delivery failures.
- Finding and correcting data errors: Detecting invalid or inconsistent records before they affect downstream systems.
- Standardizing data formats: Transforming raw inputs into consistent structures that other systems can use.
- Integrating external data sources: Connecting APIs, third-party databases, and external platforms to internal systems.
- Removing duplicate data: Identifying and resolving duplicate records to improve data quality and consistency.
Business intelligence, analytics, and data science teams are among the main users of the systems data engineers build.
Data engineering vs. data science
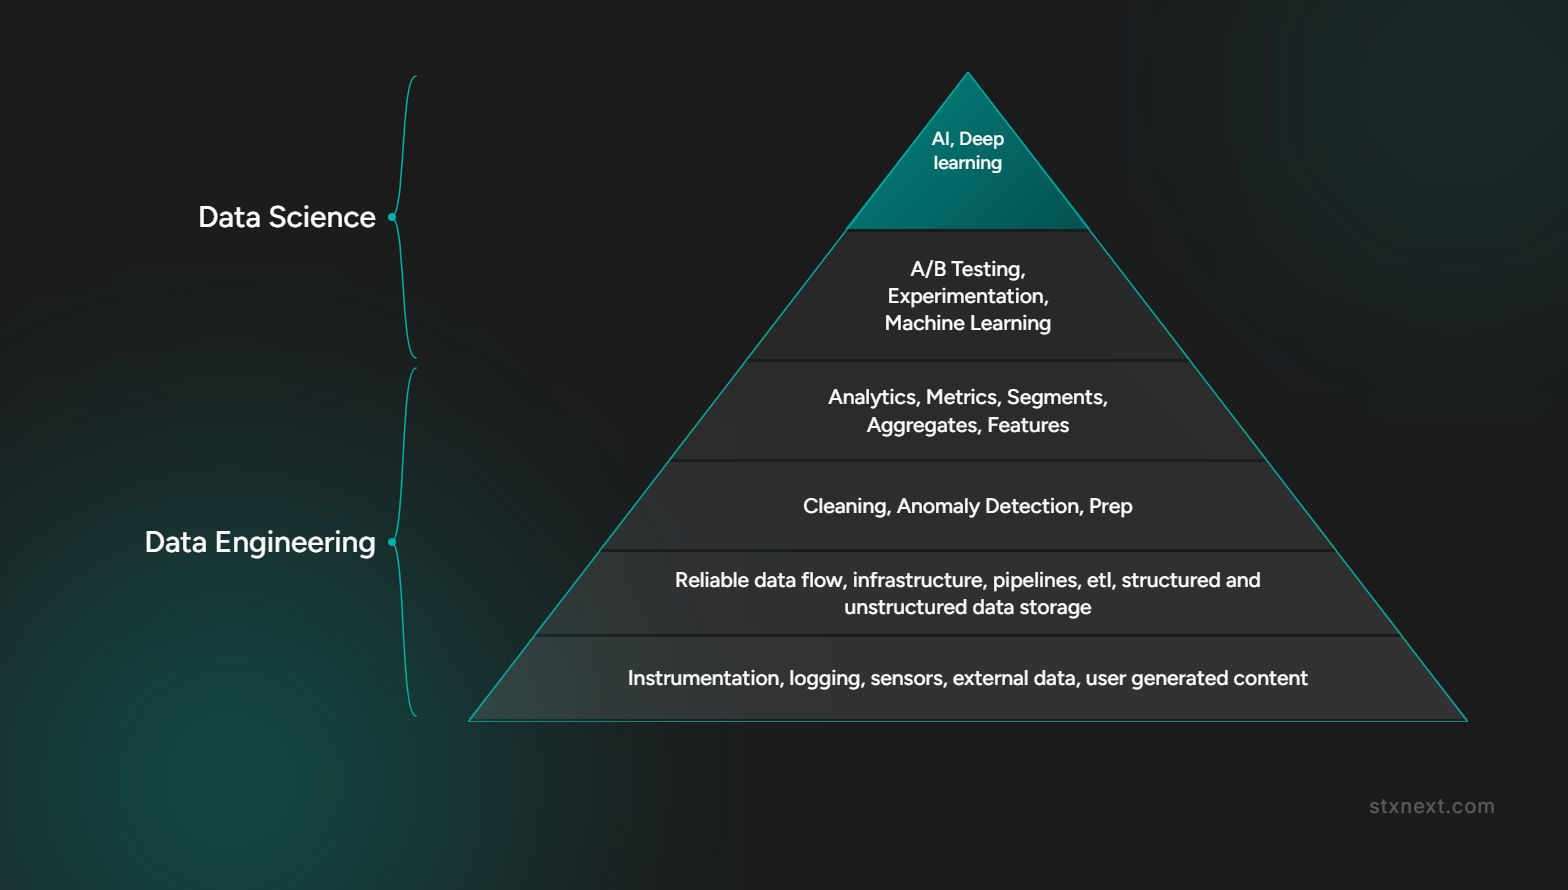
A lot has been written about data engineering vs. data science in the past, like in the image above created by Terence Shin.
In reality, they are two complementary skills. Data engineering makes data reliable and consistent for analysis, while data science uses this reliable data for analytical projects such as machine learning and data exploration.
This works very much the same way humans put their physical needs before social needs. Often, companies have to satisfy a few prerequisites that generally fall under the data engineering umbrella to create a foundation for data scientists to work on.
Therefore, it is correct to say that data scientists rely on data engineers to gather, validate, and prepare data for analysis. As a matter of fact, we could even make the claim that there can be no data science without data engineering. At least, that’s what the theory says, and it’s also the reason why Terence Shin wrote, “Data engineering is the foundation for a successful data-driven company.”
Roles often overlap in smaller teams, with data scientists building pipelines or data engineers supporting ML deployments. As teams grow, clearer ownership becomes more important. Addressing data engineering problems first also lets data scientists spend more time building and improving models instead of fixing unreliable inputs.
Key data engineering challenges and how to solve them
Now that we have covered the basics, let’s look at the primary data engineering challenges data teams face across ingestion, transformation, orchestration, and storage.
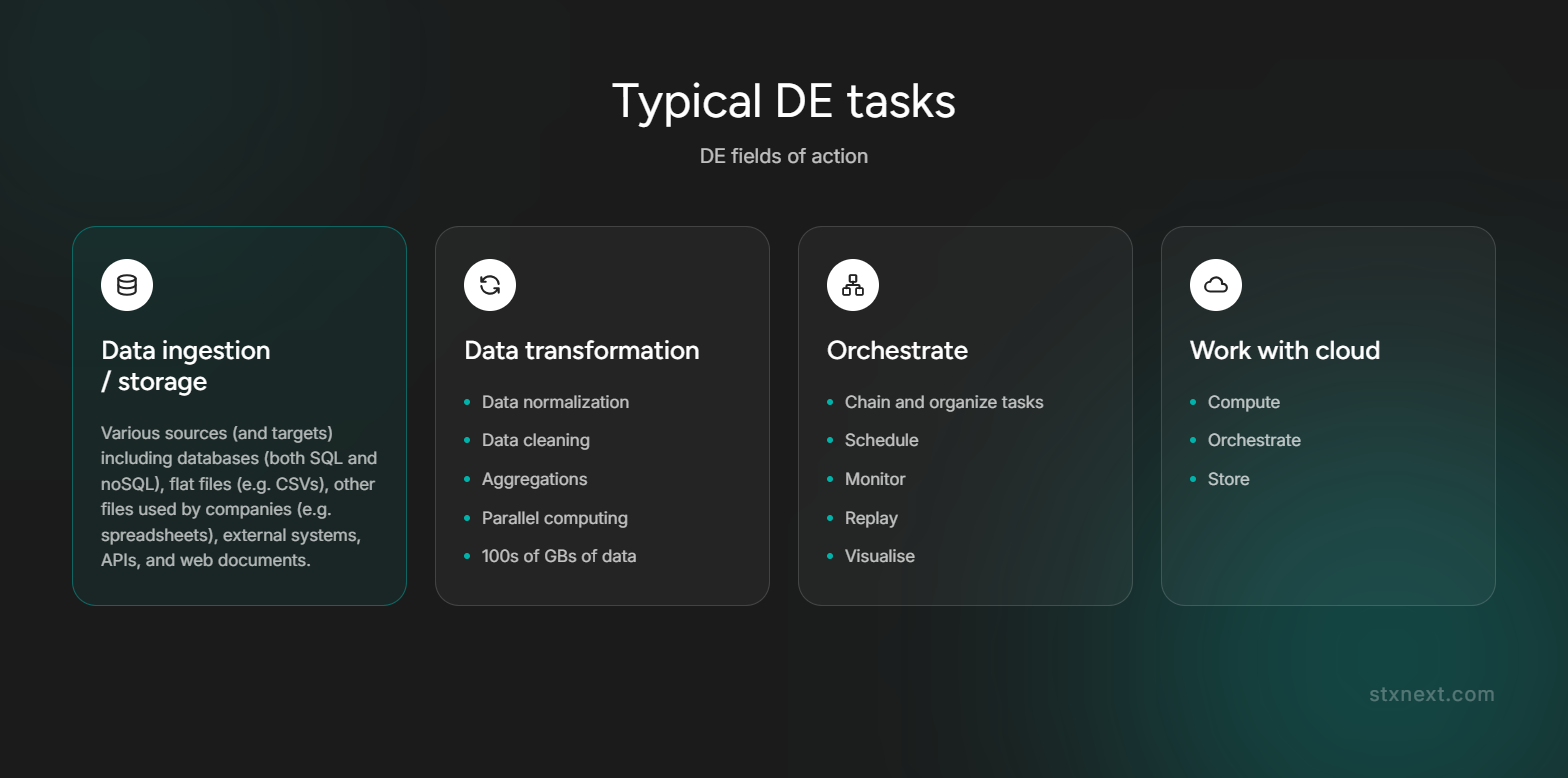
Data ingestion challenges: Handling schema drift and multi-source formats
When an upstream API changes unexpectedly or a source system sends invalid data, ingestion pipelines can fail and delay everything that depends on them. Data ingestion is therefore one of the first concerns in a data engineering project. It involves collecting data from source systems and moving it into a database, data warehouse, lakehouse, or data lake where it can be processed and used for analytics.
Data ingestion and storing data are critical components. A data lake is a vast storage repository that retains large amounts of raw, unprocessed data in its native format, making it flexible and cost-effective for different types of data and downstream processing.
Data storage is also worth mentioning here, since the core purpose of data engineering is connecting to various storage types, extracting data from it, and saving it.
One challenge is that data comes in various file formats, such as CSV, TSV, JSON, and column-oriented formats like Parquet or ORC. Data engineers may also work with unstructured data such as documents, images, or logs.
Additionally, this data might be present in various SQL and NoSQL databases, data lakes, streaming systems, APIs, or websites that need to be scraped.
Data transformation for large datasets
Without consistent data cleaning and transformation, poor-quality data can affect downstream models, reports, and dashboards. As the name suggests, data transformation refers to converting data from one format to another. Typically, most data that is collected demands some sort of adjustment so that it aligns with the system architecture standards.
Data modeling is a critical aspect of data transformation, involving the design of schemas and structures for databases to ensure optimal performance and data integrity.
So, under transformation, a data engineer will perform data normalization and cleaning to make the information more accessible to users. This includes changing or removing incorrect, duplicate, corrupted, or incomplete data in a dataset; casting data into a single type; ensuring dates are in a consistent format; and more.
As all these transformations are performed on extremely large amounts of data, there also arises a need for parallel computing.
Key challenge: At larger data volumes, heavy joins and aggregations can create memory bottlenecks or out-of-memory (OOM) errors.
The solution: Running transformations inside cloud data warehouses through an ELT approach with tools like dbt, or using distributed processing frameworks including Apache Spark and Dask.
Data orchestration and pipeline dependencies
The last step is data orchestration – combining and organizing siloed data from various storage locations and making it available for data analysis – as data pipelines comprise several elements: data sources, data transformations, and data sinks/targets.
If a pipeline component fails without proper monitoring or alerting, incomplete datasets can reach downstream business intelligence tools unnoticed.
Hence, rather than writing them as a large block of code, these data pipelines are built from separate, relatively smaller pieces using different kinds of technologies.
To achieve this, a data engineer should connect the separate pieces, schedule the process, and sometimes make decisions based on incoming data, replay part of the pipeline, or apply parallelization to some parts. Performing all these tasks demands a larger and more efficient tool than, for instance, Crontab.
Understanding data lakes for raw storage
A data lake is a centralized repository that allows you to store all your structured and unstructured data at any scale, forming a crucial part of modern data architecture. You can store your data as-is, without having to first structure it, and run different types of analytics – from dashboards and visualizations to big data processing and real-time analytics. Data lakes have become an integral part of modern data architecture and play a crucial role in data engineering.
Data engineers typically use data lakes to handle a high volume and variety of data. This includes raw data ingestion from multiple sources, whether it’s clickstream data, social media, IoT devices, or transactional data. One of the significant advantages of data lakes is their ability to store raw data in its native format while scaling to accommodate large datasets
Key features include:
- Scalability: A data lake can accommodate growing volumes of data without requiring a rigid schema upfront.
- Flexibility: Ability to store structured, semi-structured, and unstructured data.
- Cost efficiency: Object storage used for many data lake architectures can provide a relatively low-cost option for storing large volumes of data.
- Advanced analytics: Support for machine learning and data science workloads, including training machine learning models on large datasets.
- Support for multiple formats: Handles diverse file formats such as JSON, Parquet, ORC, and CSV.
Data lakes support big data analytics and provide data scientists, data engineers, and data analysts with access to data for analytical and machine learning workloads. Leading cloud providers such as Google Cloud Platform, AWS, and Azure offer services that can be used to build and operate data lake architectures
Data warehouses for curated business analytics
A data warehouse is a centralized repository that stores current and historical data from multiple sources within an organization. It's designed to support querying, data analysis activities, and data integration, providing business intelligence and valuable insights to end-users. Unlike a data lake, data warehouses store data in a structured format, making it easier to perform data modeling, data transformation, and data integration for advanced analytics.
Data engineers are responsible for designing and implementing data warehouses to ensure high data quality and performance. Data warehouses are optimized for read-heavy operations, making them suitable for reporting, complex queries, and data warehousing tasks. The data stored in a data warehouse is usually highly curated, cleaned, and transformed to meet organizational needs.
Key features include:
- Structured Storage: Data is stored using tables and schemas designed for analytical workloads and query performance.
- ETL and ELT processes: Supports data integration from multiple sources through ETL or ELT workflows.
- High Query Performance: Designed to execute analytical queries efficiently, often using column-oriented storage and other query optimizations.
- Data Consistency: Curated models, validation rules, and governance processes help maintain consistent data for business reporting.
- Support for SQL: Most data warehouses support SQL queries, making them accessible for data analysts and business users.
By combining a data lake and a data warehouse, organizations can use the strengths of both approaches, including scalable storage for diverse data and structured environments optimized for analytics.
Cloud infrastructure for data engineering
Finally, cloud computing is widely used in modern data engineering. Data engineers therefore often work with cloud services and tools available through platforms such as AWS, Google Cloud Platform (GCP), and Microsoft Azure.
Data ingestion and storage: tools and techniques
As mentioned earlier, data ingestion is about gathering and storing data for further data processing systems. That brings us to the question, “How are different databases connected?”
While raw storage engines and cloud databases physically house enterprise data, Python is the primary language used to extract, parse, and ingest that data. Thanks to its vast ecosystem of native database connectors, web parsers, and file serialization libraries, Python allows engineers to connect to virtually any data source, from relational databases and dynamic web APIs to legacy file formats, using minimal, maintainable code. See our dedicated guide on Python in Data Engineering.
Database connectors and object-relational mapping
SQLAlchemy is perhaps the most commonly used tool for connecting relational databases. An object-relational model library, it supports MySQL, MariaDB, PostgreSQL, Microsoft SQL Server, OracleDB, and SQLite. It consists of two distinct components: the Core and the Object Relational Mapper (ORM).
The Core is a fully featured SQL toolkit that allows users to interact with a wide range of relational databases APIs. In ORM, classes can be mapped to the database schema. The ORM is optional, but it is probably the main feature that makes SQLAlchemy so popular. For more complex database environments, data engineering consulting can help with connection management, schema design, and integration across different systems.
Other connectors include:
- MySQL connector for Python;
- pyodbc mssql-python for Microsoft SQL Server;
- PyMongo for MongoDB;
- redis-py for Redis.
Basically, every known database or data warehouse – whether it’s Snowflake Elastic or ClickHouse – has its own Python connector or at least recommends using a generic one.
Working with databases
Getting started with a relational database is fairly simple. The steps are quite similar for most databases, with subtle variations.
For instance, querying a MySQL database with mysql.connector involves the following steps:
- Step #1: Create a connection
- Step #2: Write a query
- Step #3: Execute it
- Step #4: Fetch the results
Similarly, when working with MongoDB, you create a client connection with MongoClient, select a database and collection, insert a document with insert_one(), and retrieve one with find_one(). With Redis, you create a connection with redis.Redis(), store a value with set(), and retrieve it with get().
It only takes a few lines of code to start working with these database systems. However, storing credentials directly in the code is bad practice. Credentials should be kept out of source code and managed through secure configuration, environment variables, or a dedicated secret manager.
Web scraping and unstructured document parsing
Data scraping is a challenge in data engineering, particularly when handling broken DOM structures, dynamic web elements, IP rate limits, and unannounced layout changes. Implementing schema validation before saving scraped data and using proxy rotation can mitigate these operational hurdles. However, BeautifulSoup can help.
A Python package for parsing HTML and XML documents, BeautifulSoup is relatively easy to work with.
Beautiful Soup can use Python’s built-in html.parser to parse an HTML document and represent it as a nested data structure. Once the document has been parsed, methods such as get_text() can extract its text content, while prettify() displays the parsed HTML in a more readable format. You can also use title to access the page title, title.string to retrieve just its text, or find_all() to find tags and strings that match specific filters.
As html.parser is a built-in parser, no extra dependencies are required. However, two other parsers are worth keeping in mind:
- html5lib – the most lenient but the slowest, to be used when an HTML file is broken;
- lxml – the fastest but has some external C dependencies.
BeautifulSoup helps data engineers easily extract text from pages, modify or replace tags, insert new ones, etc. The HTML files from the internet can be fed into BeautifulSoup, and it will transform the document into a complex tree of Python objects.
Nevertheless, you only have to deal with around four objects: Tag, NavigableString, BeautifulSoup, and Comment. There is also Scrapy, a tool that allows users to write small amounts of Python code to create a “spider” - an automated bot that can go through web pages and scrape them. With the help of Scrapy, data engineers can download, clean, and save data from the web without additional hard work.
Managing multiple file formats and streaming pipelines
Another issue during the data ingestion and storage phase is having to deal with the various data formats. This is where Pandas come in.
A software library written for Python, Pandas allows data engineers to interact with almost every known file format. Still, for a few formats, there are only reader functions, like ORC, SAS, or SPSS, and for Latex (Lay-tech), there is only the writer.
But the good news is that even if Pandas doesn’t directly support a file format, there is always some workaround solution on how that specific data can be read to Pandas DataFrames.
As far as streaming services are concerned, Apache Kafka is one of the most widely used options in data engineering. Several Python libraries are available, including kafka-python and the now-archived PyKafka, which still appears in older tutorials. confluent-kafka is another popular option, developed and maintained by Confluent, the company founded by Kafka’s original creators. For streaming services like Amazon Kinesis, AWS provides SDKs such as boto3.
Beyond real-time streaming, data engineers also work with specialized file formats, serialization tools, and other formats used to exchange or present data:
- LaTeX: A document preparation and typesetting system where you define the structure and LaTeX handles the presentation. Pandas can export DataFrames as LaTeX tables using DataFrame.to_latex().
- Feather: An Apache Arrow-based file format designed for fast storage and exchange of tabular data, including Pandas DataFrames.
- Hierarchical Data Format (HDF5): Uses a directory-like hierarchy of groups and datasets to organize large amounts of data within a file.
- Pickle: Used to serialize and deserialize Python object structures by converting them to and from a byte stream. Pickle files should only be loaded from trusted sources.
Data transformation for large datasets
Data transformation involves changing, eliminating, or fixing a dataset’s incorrect, duplicate, corrupted, or incomplete data. It can be a pretty tedious task involving extensive data manipulation.
But how is this process carried out?
Pandas can be used here, as it features a data manipulation function that can be used to access data and carry out data cleaning. However, several data engineering challenges in transforming structured and unstructured data remain, especially when scaling beyond single-machine memory.
Cleaning and manipulating missing values
Before we move on to the challenges and solutions, take a look at the following table. Here we have some general information about customers, such as name, gender, country, etc. – including other fields like “date” and a column named “param.” Data validation is crucial in ensuring the accuracy and consistency of this information.
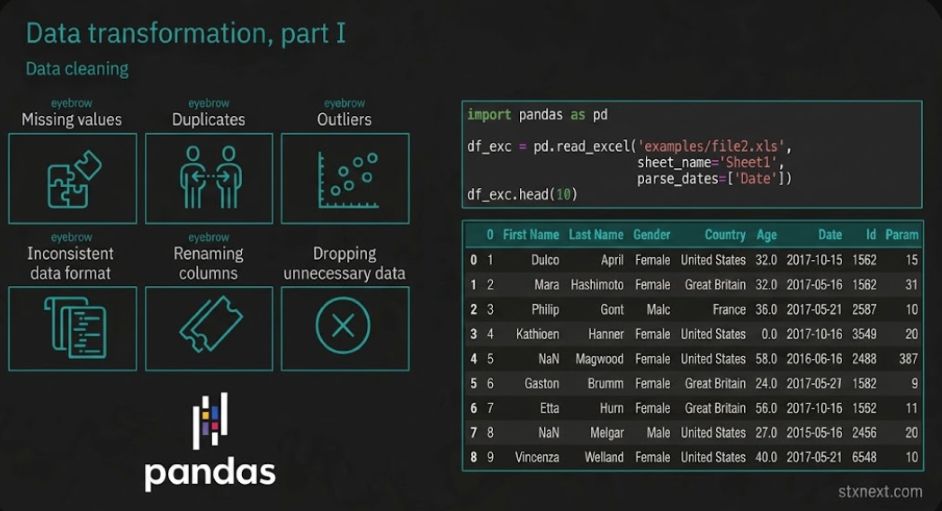
We could either use “na” or “null” to see the missing values, but it doesn't happen immediately. So, adding an “any” function at the end can help.
However, what if we want to know the exact number of missing values for a specific column? Well, we can use “sum” instead of “any,” and we'll get something like this:
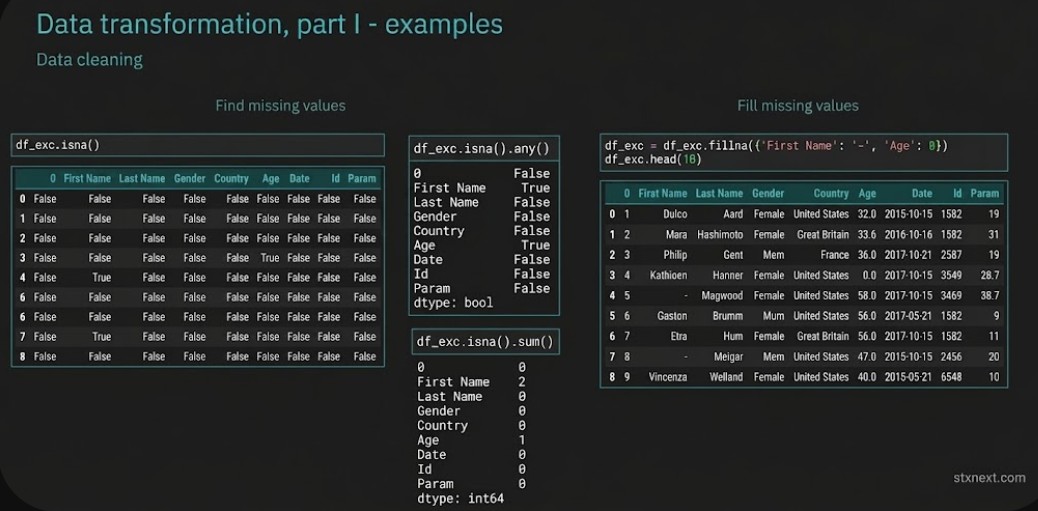
Resolving missing values across customer datasets requires systematic data-quality checks in Pandas or PySpark, including detection, profiling, imputation by replacing nulls with appropriate defaults or calculated values such as medians, and removing records with missing required fields using functions like fillna and dropna before downstream processing.
An even better way to find and fill missing values is to use Pandas.
In Pandas, missing data is represented by None and NaN. The various functions used to detect, remove, and replace null values in a Pandas DataFrame include:
- isnull()
- notnull()
- dropna()
- fillna()
- replace()
- interpolate()
Beyond finding and filling missing values, Pandas can perform functions like counting, sums, averages, joining data, applying conditioning, and more. However, these are all basic functions. So, let's move to something bigger: Apache Spark.
Parallel processing and distributed computing
Apache Spark is an extremely powerful and fast analytics engine for big data and machine learning, particularly beneficial in accessing CSV files for data analytics. Another important use case of Apache Spark is parallel processing; the tool is designed to process data in a distributed way.
Additional features include lazy evaluation and caching intermediate results in memory. If you are processing or transforming millions or billions of rows at once, Apache Spark with proper infrastructure is probably the best tool for any data engineer.
Another tool we would like to bring to your attention is Dask, which, in contrast to Apache Spark, is a pure Python framework and does not aim to be a complete ecosystem.
Dask was built because libraries like NumPy or Pandas were not originally designed to scale beyond a single CPU or to work with data that does not fit into memory. Dask allows us to efficiently run the same code in parallel, either locally or on a cluster.
Now, when it comes to parallel processing strictly on one machine, Python has threading and multiprocessing options:
- Threading: In standard CPython, the Global Interpreter Lock generally prevents multiple threads from executing Python code in parallel, although threads are still useful for concurrent I/O-bound work.
- Multiprocessing: On the other hand, multiprocessing is designed to do things in true parallel, making it convenient for CPU-bound tasks, like performing aggregations on millions of rows or processing hundreds of images in big data environments.
To explore how to structure these transformation steps into maintainable, production-ready systems, read our comprehensive guide on data engineering best practices.
What is data orchestration?
When pipeline tasks fail silently or run out of sequence, downstream datasets can become incomplete or outdated, affecting reports and analytics. Data orchestration tools help prevent this by managing task dependencies, execution order, retries, and alerts.
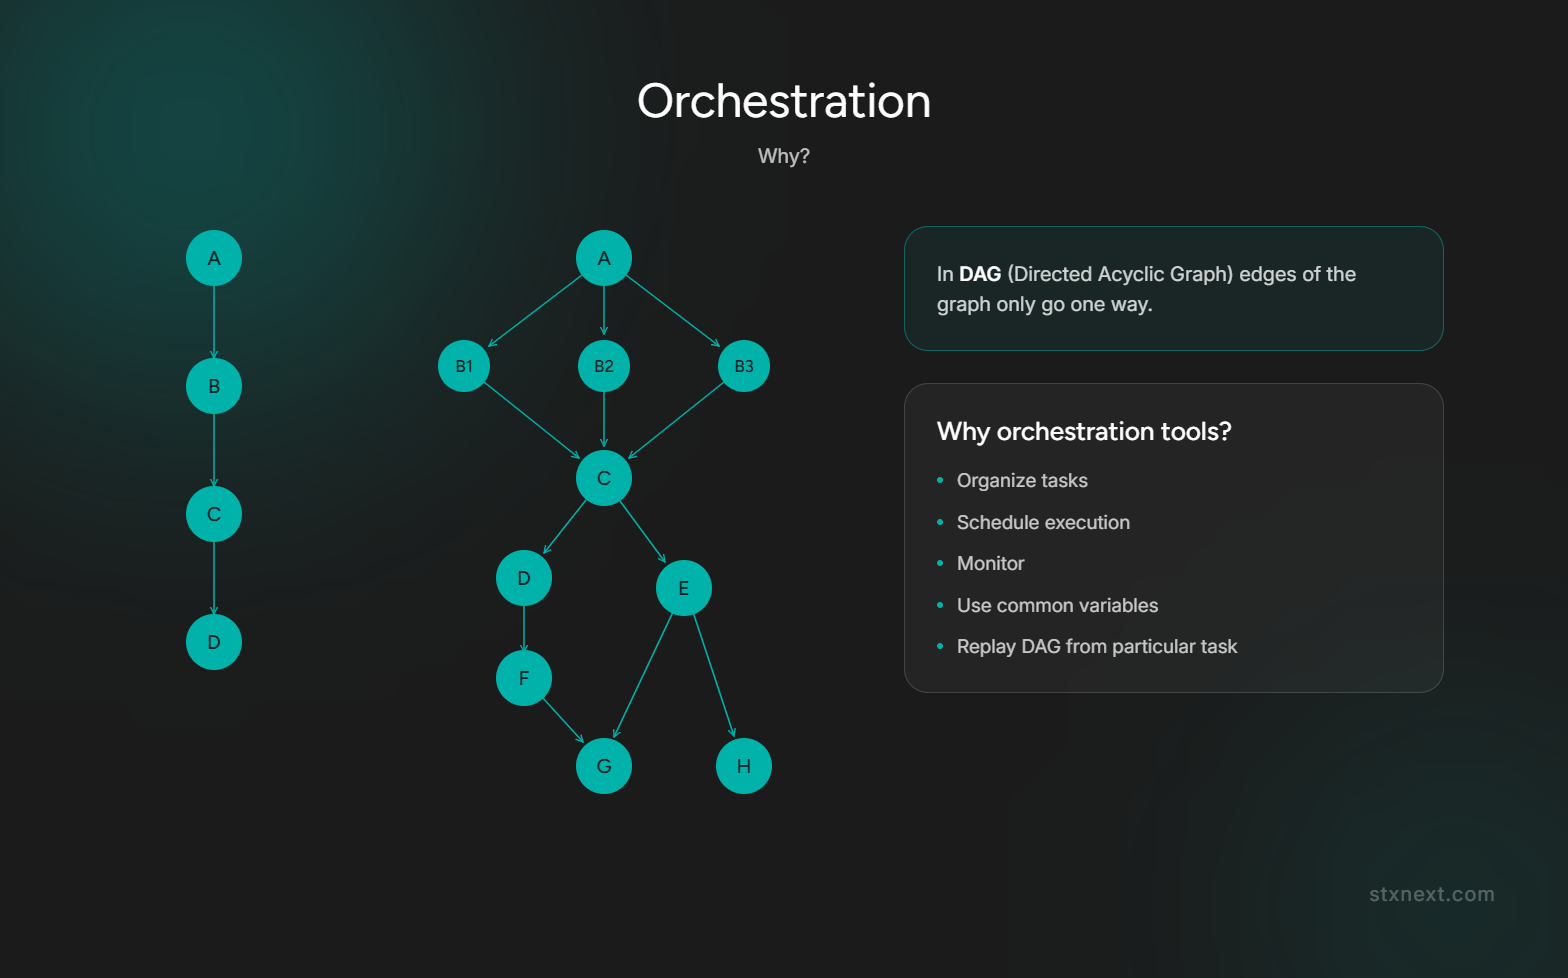
While SQL handles modern cloud data warehouse transformations, Python remains the undisputed language of data engineering orchestration and glue code. Thanks to its rich ecosystem of client libraries, API wrappers, and native framework support, Python enables engineers to connect disparate databases, handle complex data formats, and define end-to-end pipelines as code.
Imagine a data pipeline of tasks that should be run once a day or once a week. These tasks should be run in a specific order. However, they grow and become a network of tasks with dynamic branches called DAGs – Directed Acyclic Graphs. Orchestration tools use DAGs to define how pipeline tasks depend on one another, so tasks run in the correct order without circular dependencies.
But that’s not all. Other than organizing tasks into DAGs and scheduling them, we also often want to:
- be able to monitor them easily;
- dynamically parallel some tasks;
- wait for a file to appear before it can be processed;
- use some common or shared variables;
- in case of failure, replay DAG starting from a particular task.
So, which Python-based tool should be used to address this challenge?
Orchestration tools and framework selection
You have plenty of orchestration tools to choose from. You may use Apache Airflow, Dagster, Luigi, Prefect, Mage, or Kedro, while Kubeflow Pipelines supports ML-specific workflow orchestration. MLflow serves a different role, focusing primarily on experiment tracking and model lifecycle management.
Nevertheless, Apache Airflow happens to be the most popular option, as it has a wide array of features. On the other hand, Luigi (designed by Spotify) and Prefect are much easier to get started with, though they lack some of Airflow’s features.
For instance, Apache Airflow can run multiple DAGs at once and trigger a workflow at specified intervals or times. It’s also much simpler to build more complex data pipelines where some tasks run in parallel while others wait for their dependencies to complete.
Additionally, Prefect is open-core, while Luigi and Airflow are both open-source.
Now, if you want an alternative for Airflow or any other workflow engine, our pick is Dagster. A relatively new tool, Dagster schedules, orders, and monitors computations.
Lastly, Kubeflow and MLflow serve more niche requirements related to deploying machine learning models and tracking experiments, while Kedro provides a structured framework for writing modular data code rather than acting as a standalone scheduling orchestrator.
Data engineering challenges in cloud infrastructure
By now, Python has proven itself to be good enough to encourage cloud computing platform providers to use it for implementing and controlling their services.
Therefore, it is only right that we take a closer look at how Python can be made to run on the cloud. As you might already know, there are three leading cloud providers on the market: AWS, Google Cloud Platform, and Microsoft Azure.
When it comes to computing services, all three providers have services called functions (Lambda, Cloud, and Azure Functions), and all of them support Python. With features like container image support in AWS Lambda, engineers can package heavy Python data processing libraries (Pandas, PyArrow, NumPy) and run lightweight ETL jobs on demand.
For instance, an AWS Lambda function can respond when a file is added to an Amazon S3 bucket and then trigger an Apache Airflow DAG through the Airflow API. Alternatively, Lambda can run image-processing code after a photo is uploaded to S3, save the processed image back to the bucket, and write event metadata to Amazon RDS.
Another question you might be asking yourself is, “Can we use Apache Spark in the cloud?”
Yes, we can. All three cloud providers offer us services designed to run and manage big data frameworks, including Apache Spark for distributed data processing. This includes managed and serverless options like AWS EMR Serverless, Google Cloud Managed Service for Apache Spark, and Azure Synapse Analytics, alongside platforms such as Databricks. Teams looking to combine cloud raw storage with structured query performance can explore our data lakehouse development services.
Furthermore, if you wish to write custom code to create, manage, and interact with cloud services, AWS offers the Boto3 library, while GCP and Azure provide service-specific Python SDK packages, such as google-cloud-bigquery and azure-storage-blob, so developers can install only the components they need.
Lastly, when it comes to orchestrators, all three major cloud providers offer managed Apache Airflow options:
- AWS: Offers Amazon MWAA (Managed Workflows for Apache Airflow).
- GCP: Offers Managed Service for Apache Airflow, previously known as Cloud Composer.
- Azure: Offers managed Apache Airflow jobs through Microsoft Fabric Data Factory, the successor to Azure Data Factory’s Workflow Orchestration Manager. Azure Data Factory also provides its own native pipeline orchestration.
In simple words, all the big cloud players greatly accommodate Python users in their solutions.
Final thoughts on common data engineering challenges and their solutions
Thank you for reading this article!
We’re always looking to support businesses with tapping into new possibilities using this fantastic programming language.
Whether you are building pipelines from scratch or optimizing existing infrastructure, navigating these data engineering challenges requires a clear architectural vision. If you want to accelerate your data initiatives or optimize pipeline performance, explore our data engineering services to see how our team can help you build scalable, production-ready systems.


